Backpropagation November 5, 2023
The following are my notes I prepared for the students as part of tutoring the Neural Networks class at Saarland University in fall 2023. Originally typset in LaTeX I
decided that they are also a nice addition to my website. Most of the content is a more detailed discussion of the backpropagation section in Christopher Bishops excellent PRML Bishop, 2006
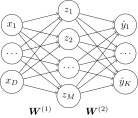
Consider a fully connected feed-forward neural network with one hidden
layer with M M M D D D K K K Figure 1
a ( 1 ) = W ( 1 ) x a m ( 1 ) = ∑ d = 1 D W m d ( 1 ) x d z = h ( 1 ) ( a ( 1 ) ) z m = h ( 1 ) ( a m ( 1 ) ) a ( 2 ) = W ( 2 ) z a k ( 2 ) = ∑ m = 1 M W k m ( 2 ) z m y ^ = h ( 2 ) ( a ( 2 ) ) y ^ k = h ( 2 ) ( a k ( 2 ) ) \begin{aligned}
\mathbf{a}^{(1)} &= \boldsymbol{W}^{(1)}\mathbf{x} & a^{(1)}_m &= \sum_{d=1}^D \boldsymbol{W}^{(1)}_{md}x_d\\
\mathbf{z} &= h^{(1)} \left(\mathbf{a}^{(1)}\right) & z_m &= h^{(1)}\left(a^{(1)}_m\right)\\
\mathbf{a}^{(2)} &= \boldsymbol{W}^{(2)}\mathbf{z} & a^{(2)}_k &= \sum_{m=1}^M \boldsymbol{W}^{(2)}_{km}z_m\\
\mathbf{\hat{y}} &= h^{(2)} \left(\mathbf{a}^{(2)}\right) & \hat{y}_k &= h^{(2)}\left(a^{(2)}_k\right)
\end{aligned} a ( 1 ) z a ( 2 ) y ^ = W ( 1 ) x = h ( 1 ) ( a ( 1 ) ) = W ( 2 ) z = h ( 2 ) ( a ( 2 ) ) a m ( 1 ) z m a k ( 2 ) y ^ k = d = 1 ∑ D W m d ( 1 ) x d = h ( 1 ) ( a m ( 1 ) ) = m = 1 ∑ M W km ( 2 ) z m = h ( 2 ) ( a k ( 2 ) ) Here x ∈ R D , a ( 1 ) , z ∈ R M , a ( 2 ) , y ^ ∈ R K \mathbf{x} \in \mathbb{R}^{D}, \mathbf{a}^{(1)}, \mathbf{z} \in \mathbb{R}^{M}, \mathbf{a}^{(2)}, \mathbf{\hat{y}} \in \mathbb{R}^{K} x ∈ R D , a ( 1 ) , z ∈ R M , a ( 2 ) , y ^ ∈ R K W ( 1 ) ∈ R M × D , W ( 2 ) ∈ R K × M \boldsymbol{W}^{(1)} \in \mathbb{R}^{M \times D}, \boldsymbol{W}^{(2)} \in \mathbb{R}^{K \times M} W ( 1 ) ∈ R M × D , W ( 2 ) ∈ R K × M h ( 1 ) h^{(1)} h ( 1 ) a ( 1 ) \mathbf{a}^{(1)} a ( 1 ) h ( 2 ) h^{(2)} h ( 2 ) J \mathrm{J} J
J ( { ( x i , y i ) } i = 1 N ; W ( 1 ) , W ( 2 ) ) = ∑ n = 1 N J n ( x n , y ^ n ; W ( 1 ) , W ( 2 ) ) \mathrm{J}\left({\{(\mathbf{x}_i, \mathbf{y}_i)\}_{i=1}^N; \boldsymbol{W}^{(1)}, \boldsymbol{W}^{(2)}}\right) = \sum_{n=1}^N \mathrm{J}_n \left( \mathbf{x}_n, \mathbf{\hat{y}}_n ; \boldsymbol{W}^{(1)}, \boldsymbol{W}^{(2)} \right) J ( {( x i , y i ) } i = 1 N ; W ( 1 ) , W ( 2 ) ) = n = 1 ∑ N J n ( x n , y ^ n ; W ( 1 ) , W ( 2 ) ) To minimize the loss we are interested in gradients of the weight
matrices. From now on we will only consider the loss J n \mathrm{J}_n J n ( x n , y ^ n ) (\mathbf{x}_n, \mathbf{\hat{y}}_n) ( x n , y ^ n ) W j i ( 2 ) \boldsymbol{W}^{(2)}_{ji} W ji ( 2 ) W j i ( 2 ) \boldsymbol{W}^{(2)}_{ji} W ji ( 2 ) y ^ \mathbf{\hat{y}} y ^ a j ( 2 ) a_j^{(2)} a j ( 2 )
∂ J n ∂ W j i ( 2 ) = ∂ J n ∂ a j ( 2 ) ∂ a j ( 2 ) ∂ W j i ( 2 ) \begin{aligned}
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(2)}_{ji}} &= \frac{\partial \mathrm{J}_n}{\partial a_j^{(2)}} \frac{\partial a_j^{(2)}}{\partial \boldsymbol{W}^{(2)}_{ji}}
\end{aligned} ∂ W ji ( 2 ) ∂ J n = ∂ a j ( 2 ) ∂ J n ∂ W ji ( 2 ) ∂ a j ( 2 ) We can further simplify by again applying the chain rule, this time to the first term:
= ∂ J n ∂ y ^ j ∂ y ^ j ∂ a j ( 2 ) ∂ a j ( 2 ) ∂ W j i ( 2 ) \begin{aligned}
&= \frac{\partial \mathrm{J}_n}{\partial \hat{y}_j} \frac{\partial \hat{y}_j}{\partial a_j^{(2)}} \frac{\partial a_j^{(2)}}{\partial \boldsymbol{W}^{(2)}_{ji}}
\end{aligned} = ∂ y ^ j ∂ J n ∂ a j ( 2 ) ∂ y ^ j ∂ W ji ( 2 ) ∂ a j ( 2 ) Here ∂ J n ∂ y ^ j \frac{\partial \mathrm{J}_n}{\partial \hat{y}_j} ∂ y ^ j ∂ J n
∂ J n ∂ y ^ j = { y ^ j − y n j when J n = 1 2 ( y ^ j − y n j ) 2 − y n j y ^ j when J n = ∑ k = 1 K y n k log ( y ^ k ) \frac{\partial \mathrm{J}_n}{\partial \hat{y}_j} = \begin{cases}
\hat{y}_j - y_{nj} & \text{when } \mathrm{J}_n = \frac{1}{2}\left( \hat{y}_j - y_{nj} \right)^2\\
-\frac{y_{nj}}{\hat{y}_j} & \text{when } \mathrm{J}_n = \sum_{k=1}^K y_{nk} \log (\hat{y}_k)
\end{cases} ∂ y ^ j ∂ J n = { y ^ j − y nj − y ^ j y nj when J n = 2 1 ( y ^ j − y nj ) 2 when J n = ∑ k = 1 K y nk log ( y ^ k ) The second term
∂ y ^ j ∂ a j ( 2 ) \frac{\partial \hat{y}_j}{\partial a_j^{(2)}} ∂ a j ( 2 ) ∂ y ^ j h ( 2 ) h^{(2)} h ( 2 ) h ( 2 ) ( a ( 2 ) ) = a ( 2 ) h^{(2)}\left(\mathbf{a^{(2)}} \right) = \mathbf{a^{(2)}} h ( 2 ) ( a ( 2 ) ) = a ( 2 )
∂ a j ( 2 ) ∂ W j i ( 2 ) = ∂ ∂ W j i ( 2 ) ( ∑ m = 1 M W j m ( 2 ) z m ) = z i \begin{aligned}
\frac{\partial a_j^{(2)}}{\partial \boldsymbol{W}^{(2)}_{ji}} = \frac{\partial }{\partial \boldsymbol{W}^{(2)}_{ji}} \left( \sum_{m=1}^M \boldsymbol{W}^{(2)}_{jm}z_m \right)
= z_i
\end{aligned} ∂ W ji ( 2 ) ∂ a j ( 2 ) = ∂ W ji ( 2 ) ∂ ( m = 1 ∑ M W jm ( 2 ) z m ) = z i Therefore the partial derivative for entry i j ij ij W ( 2 ) \boldsymbol{W}^{(2)} W ( 2 )
∂ J n ∂ W j i ( 2 ) = ∂ J n ∂ a j ( 2 ) ∂ a j ( 2 ) ∂ W j i ( 2 ) = [ ∂ J n ∂ y ^ j ∂ y ^ j ∂ a j ( 2 ) ] ⋅ z i = [ ∂ J n ∂ y ^ j ⋅ h ( 2 ) ′ ( a j ( 2 ) ) ] ⏟ δ j ( 2 ) ⋅ z i = δ j ( 2 ) ⋅ z i \begin{align*}
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(2)}_{ji}} &= \frac{\partial \mathrm{J}_n}{\partial a_j^{(2)}} \frac{\partial a_j^{(2)}}{\partial \boldsymbol{W}^{(2)}_{ji}} \\
&=\left[ \frac{\partial \mathrm{J}_n}{\partial \hat{y}_j} \frac{\partial \hat{y}_j}{\partial a_j^{(2)}} \right] \cdot z_i \\
&= \underbrace{\left[ \frac{\partial \mathrm{J}_n}{\partial \hat{y}_j} \cdot h^{(2)\prime} \left(a_j^{(2)} \right) \right]}_{\delta^{(2)}_j} \cdot z_i
= \delta^{(2)}_j \cdot z_i
\end{align*} ∂ W ji ( 2 ) ∂ J n = ∂ a j ( 2 ) ∂ J n ∂ W ji ( 2 ) ∂ a j ( 2 ) = [ ∂ y ^ j ∂ J n ∂ a j ( 2 ) ∂ y ^ j ] ⋅ z i = δ j ( 2 ) [ ∂ y ^ j ∂ J n ⋅ h ( 2 ) ′ ( a j ( 2 ) ) ] ⋅ z i = δ j ( 2 ) ⋅ z i We denote the term with
δ j ( 2 ) : = ∂ J n ∂ a j ( 2 ) \delta^{(2)}_j := \frac{\partial \mathrm{J}_n}{\partial a_j^{(2)}} δ j ( 2 ) := ∂ a j ( 2 ) ∂ J n error term.
The calculation of the partial derivatives of W j i ( 1 ) \boldsymbol{W}^{(1)}_{ji} W ji ( 1 ) W j i ( 1 ) \boldsymbol{W}^{(1)}_{ji} W ji ( 1 ) W j i ( 1 ) \boldsymbol{W}^{(1)}_{ji} W ji ( 1 ) y ^ \mathbf{\hat{y}} y ^ a j ( 1 ) a^{(1)}_j a j ( 1 )
∂ J n ∂ W j i ( 1 ) = ∂ J n ∂ a j ( 1 ) ∂ a j ( 1 ) ∂ W j i ( 1 ) \frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(1)}_{ji}} = \frac{\partial \mathrm{J}_n}{\partial a^{(1)}_j} \frac{\partial a^{(1)}_j}{\partial \boldsymbol{W}^{(1)}_{ji}} ∂ W ji ( 1 ) ∂ J n = ∂ a j ( 1 ) ∂ J n ∂ W ji ( 1 ) ∂ a j ( 1 ) To begin with, we focus on the first term. Notice that J n \mathrm{J}_n J n a j ( 1 ) a^{(1)}_j a j ( 1 ) z j z_j z j
∂ J n ∂ a j ( 1 ) = ∂ J n ∂ z j ∂ z j ∂ a j ( 1 ) \begin{aligned}
\frac{\partial \mathrm{J}_n}{\partial a^{(1)}_j} &= \frac{\partial \mathrm{J}_n}{\partial z_j} \frac{\partial z_j}{\partial a^{(1)}_j}
\end{aligned} ∂ a j ( 1 ) ∂ J n = ∂ z j ∂ J n ∂ a j ( 1 ) ∂ z j This time however, z j z_j z j y k y_k y k a k ( 2 ) = ∑ m = 1 M W k m ( 2 ) z m a^{(2)}_k = \sum_{m=1}^M \boldsymbol{W}^{(2)}_{km}z_m a k ( 2 ) = ∑ m = 1 M W km ( 2 ) z m ∂ J n ∂ z j \frac{\partial \mathrm{J}_n}{\partial z_j} ∂ z j ∂ J n a k ( 2 ) a^{(2)}_k a k ( 2 ) k = 1 , … , K k=1,\dots, K k = 1 , … , K
= ∑ k = 1 K ∂ J n ∂ a k ( 2 ) ∂ a k ( 2 ) ∂ z j ∂ z j ∂ a j ( 1 ) \begin{aligned}
&= \sum_{k=1}^{K} \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_k} \frac{\partial a^{(2)}_k}{\partial z_j} \frac{\partial z_j}{\partial a^{(1)}_j}
\end{aligned} = k = 1 ∑ K ∂ a k ( 2 ) ∂ J n ∂ z j ∂ a k ( 2 ) ∂ a j ( 1 ) ∂ z j By definition, we know ∂ J n ∂ a k ( 2 ) = δ k ( 2 ) \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_k} = \delta^{(2)}_k ∂ a k ( 2 ) ∂ J n = δ k ( 2 ) ∂ z j ∂ a j ( 1 ) = h ( 1 ) ′ ( a j ( 1 ) ) \frac{\partial z_j}{\partial a^{(1)}_j} = h^{(1)\prime}(a^{(1)}_j) ∂ a j ( 1 ) ∂ z j = h ( 1 ) ′ ( a j ( 1 ) ) ∂ a k ( 2 ) ∂ z j \frac{\partial a^{(2)}_k}{\partial z_j} ∂ z j ∂ a k ( 2 ) W k j ( 2 ) \boldsymbol{W}^{(2)}_{kj} W kj ( 2 )
= ∑ k = 1 K δ k ( 2 ) W k j ( 2 ) h ( 1 ) ′ ( a j ( 1 ) ) = h ( 1 ) ′ ( a j ( 1 ) ) ⋅ ∑ k = 1 K W k j ( 2 ) δ k ( 2 ) \begin{aligned}
&= \sum_{k=1}^{K} \delta^{(2)}_k\boldsymbol{W}^{(2)}_{kj} h^{(1)\prime}\left(a^{(1)}_j\right)\\
&= h^{(1)\prime}\left(a^{(1)}_j\right) \cdot \sum_{k=1}^{K} \boldsymbol{W}^{(2)}_{kj} \delta^{(2)}_k
\end{aligned} = k = 1 ∑ K δ k ( 2 ) W kj ( 2 ) h ( 1 ) ′ ( a j ( 1 ) ) = h ( 1 ) ′ ( a j ( 1 ) ) ⋅ k = 1 ∑ K W kj ( 2 ) δ k ( 2 ) Only the partial derivative
∂ a j ( 1 ) ∂ W j i ( 1 ) \frac{\partial a^{(1)}_j}{\partial \boldsymbol{W}^{(1)}_{ji}} ∂ W ji ( 1 ) ∂ a j ( 1 )
∂ a j ( 1 ) ∂ W j i ( 1 ) = ∂ ∂ W j i ( 1 ) ( ∑ d = 1 D W j d ( 1 ) x d ) = x d \frac{\partial a^{(1)}_j}{\partial \boldsymbol{W}^{(1)}_{ji}} = \frac{\partial }{\partial \boldsymbol{W}^{(1)}_{ji}} \left( \sum_{d=1}^D \boldsymbol{W}^{(1)}_{jd}x_d \right) = x_d ∂ W ji ( 1 ) ∂ a j ( 1 ) = ∂ W ji ( 1 ) ∂ ( d = 1 ∑ D W j d ( 1 ) x d ) = x d Consequently, every entry i j ij ij W ( 1 ) \boldsymbol{W}^{(1)} W ( 1 )
∂ J n ∂ W j i ( 1 ) = ∂ J n ∂ a j ( 1 ) ∂ a j ( 1 ) ∂ W j i ( 1 ) = [ ∑ k = 1 K ∂ J n ∂ a k ( 2 ) ∂ a k ( 2 ) ∂ z j ∂ z j ∂ a j ( 1 ) ] ∂ a j ( 1 ) ∂ W j i ( 1 ) = [ ∑ k = 1 K ∂ J n ∂ a k ( 2 ) ∂ a k ( 2 ) ∂ z j ∂ z j ∂ a j ( 1 ) ] ⋅ x d = [ h ( 1 ) ′ ( a j ( 1 ) ) ⋅ ∑ k = 1 K W k j ( 2 ) δ k ( 2 ) ] ⏟ δ j ( 1 ) ⋅ x d = δ j ( 1 ) ⋅ x d \begin{align*}
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(1)}_{ji}} &= \frac{\partial \mathrm{J}_n}{\partial a^{(1)}_j} \frac{\partial a^{(1)}_j}{\partial \boldsymbol{W}^{(1)}_{ji}} \\
&=\left[ \sum_{k=1}^{K} \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_k} \frac{\partial a^{(2)}_k}{\partial z_j} \frac{\partial z_j}{\partial a^{(1)}_j} \right] \frac{\partial a^{(1)}_j}{\partial \boldsymbol{W}^{(1)}_{ji}}\\
&=\left[ \sum_{k=1}^{K} \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_k} \frac{\partial a^{(2)}_k}{\partial z_j} \frac{\partial z_j}{\partial a^{(1)}_j} \right] \cdot x_d\\
&=
\underbrace{\left[ h^{(1)\prime}\left(a^{(1)}_j\right) \cdot \sum_{k=1}^{K} \boldsymbol{W}^{(2)}_{kj} \delta^{(2)}_k \right]}_{\delta^{(1)}_j}
\cdot x_d = \delta^{(1)}_j \cdot x_d
\end{align*} ∂ W ji ( 1 ) ∂ J n = ∂ a j ( 1 ) ∂ J n ∂ W ji ( 1 ) ∂ a j ( 1 ) = [ k = 1 ∑ K ∂ a k ( 2 ) ∂ J n ∂ z j ∂ a k ( 2 ) ∂ a j ( 1 ) ∂ z j ] ∂ W ji ( 1 ) ∂ a j ( 1 ) = [ k = 1 ∑ K ∂ a k ( 2 ) ∂ J n ∂ z j ∂ a k ( 2 ) ∂ a j ( 1 ) ∂ z j ] ⋅ x d = δ j ( 1 ) [ h ( 1 ) ′ ( a j ( 1 ) ) ⋅ k = 1 ∑ K W kj ( 2 ) δ k ( 2 ) ] ⋅ x d = δ j ( 1 ) ⋅ x d Note, although we assumed a single hidden layer neural
network, the partial derivatives for deeper layers take the same form as
for W ( 1 ) \boldsymbol{W}^{(1)} W ( 1 ) x = z ( 0 ) = h ( 0 ) ( a ( 0 ) ) \mathbf{x} = \mathbf{z}^{(0)} = h^{(0)}\left(\mathbf{a}^{(0)}\right) x = z ( 0 ) = h ( 0 ) ( a ( 0 ) ) a ( 0 ) = W 0 z ( − 1 ) \mathbf{a}^{(0)} = \boldsymbol{W}^{0}\mathbf{z}^{(-1)} a ( 0 ) = W 0 z ( − 1 )
Consider a simple linear regression network with one hidden layer, ReLU
activation functions and one output unit, i.e.
z = h ( 1 ) ( a ( 1 ) ) = max ( 0 , a ( 1 ) ) y ^ = h ( 2 ) ( a ( 2 ) ) = a ( 2 ) \begin{aligned}
\mathbf{z} &= h^{(1)}\left(\mathbf{a}^{(1)}\right) = \max\left(0, \mathbf{a}^{(1)} \right)\\
\hat{y}&= h^{(2)}\left(a^{(2)}\right) = a^{(2)}
\end{aligned} z y ^ = h ( 1 ) ( a ( 1 ) ) = max ( 0 , a ( 1 ) ) = h ( 2 ) ( a ( 2 ) ) = a ( 2 ) The error function is given by the squared difference
J n ( x n , y n ) = 1 2 ( y ^ n − y n ) 2 \mathrm{J}_n(\mathbf{x}_n, y_n) = \frac{1}{2} (\hat{y}_n - y_n)^2 J n ( x n , y n ) = 2 1 ( y ^ n − y n ) 2 From (7) δ ( 2 ) \delta^{(2)} δ ( 2 )
δ ( 2 ) = ∂ J n ∂ y ^ ⋅ h ( 2 ) ′ ( a ( 2 ) ) = ∂ J n ∂ y ^ = ( y ^ n − y n ) \delta^{(2)} = \frac{\partial \mathrm{J}_n}{\partial \hat{y}} \cdot h^{(2)\prime}\left(a^{(2)} \right) = \frac{\partial \mathrm{J}_n}{\partial \hat{y}} = (\hat{y}_n - y_n) δ ( 2 ) = ∂ y ^ ∂ J n ⋅ h ( 2 ) ′ ( a ( 2 ) ) = ∂ y ^ ∂ J n = ( y ^ n − y n ) where we used the fact that h ( 2 ) ′ ( a ( 2 ) ) = 1 h^{(2)\prime}\left(a^{(2)} \right) = 1 h ( 2 ) ′ ( a ( 2 ) ) = 1
∂ J n ∂ W 1 i ( 2 ) = δ ( 2 ) ⋅ z i = ( y ^ n − y n ) ⋅ z i \frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(2)}_{1i}} = \delta^{(2)} \cdot z_i = (\hat{y}_n - y_n) \cdot z_i ∂ W 1 i ( 2 ) ∂ J n = δ ( 2 ) ⋅ z i = ( y ^ n − y n ) ⋅ z i We write W 1 i ( 2 ) \boldsymbol{W}^{(2)}_{1i} W 1 i ( 2 ) W i ( 2 ) \boldsymbol{W}^{(2)}_{i} W i ( 2 ) W ( 1 ) \boldsymbol{W}^{(1)} W ( 1 ) ∂ z j ∂ a j ( 1 ) \frac{\partial z_j}{\partial a^{(1)}_j} ∂ a j ( 1 ) ∂ z j
∂ z j ∂ a j ( 1 ) = h ( 1 ) ′ ( a j ( 1 ) ) = ReLU ′ ( a j ( 1 ) ) = { 1 if a j ( 1 ) > 0 0 otherwise \begin{aligned}
\frac{\partial z_j}{\partial a^{(1)}_j} &= h^{(1)\prime}\left(a^{(1)}_j\right) = \text{ReLU}'\left( a^{(1)}_j \right) = \begin{cases}
1 & \text{if } a^{(1)}_j > 0 \\
0 & \text{otherwise}
\end{cases}
\end{aligned} ∂ a j ( 1 ) ∂ z j = h ( 1 ) ′ ( a j ( 1 ) ) = ReLU ′ ( a j ( 1 ) ) = { 1 0 if a j ( 1 ) > 0 otherwise Making use of (13)
∂ J n ∂ W j i ( 1 ) = ReLU ′ ( a j ( 1 ) ) ⋅ ∑ k = 1 K W k j ( 2 ) δ k ( 2 ) ∂ J n ∂ W j i ( 1 ) = ReLU ′ ( a j ( 1 ) ) ⋅ W 1 j ( 2 ) δ ( 2 ) = ReLU ′ ( a j ( 1 ) ) ⋅ W 1 j ( 2 ) ( y ^ n − y n ) = I [ a j ( 1 ) > 0 ] ⋅ W 1 j ( 2 ) ( y ^ n − y n ) \begin{aligned}
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(1)}_{ji}} &= \text{ReLU}'\left( a^{(1)}_j \right) \cdot \sum_{k=1}^K \boldsymbol{W}_{kj}^{(2)} \delta^{(2)}_k\\
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(1)}_{ji}} &=\text{ReLU}'\left( a^{(1)}_j \right) \cdot \boldsymbol{W}_{1j}^{(2)} \delta^{(2)}\\
&= \text{ReLU}'\left( a^{(1)}_j \right) \cdot \boldsymbol{W}_{1j}^{(2)} (\hat{y}_n - y_n)\\
&= \mathbb{I}\left[ a^{(1)}_j > 0 \right] \cdot \boldsymbol{W}_{1j}^{(2)} (\hat{y}_n - y_n)
\end{aligned} ∂ W ji ( 1 ) ∂ J n ∂ W ji ( 1 ) ∂ J n = ReLU ′ ( a j ( 1 ) ) ⋅ k = 1 ∑ K W kj ( 2 ) δ k ( 2 ) = ReLU ′ ( a j ( 1 ) ) ⋅ W 1 j ( 2 ) δ ( 2 ) = ReLU ′ ( a j ( 1 ) ) ⋅ W 1 j ( 2 ) ( y ^ n − y n ) = I [ a j ( 1 ) > 0 ] ⋅ W 1 j ( 2 ) ( y ^ n − y n ) Where the sum vanishes because we have only one output unit.
This time we consider a binary classification task, i.e. we use the
binary cross entropy loss and sigmoid activation function in the last
layer. The network structure is the same as in Example 1.
J n ( x n , y n ) = − y n ⋅ log y ^ n − ( 1 − y n ) ⋅ log ( 1 − y ^ n ) J_n(\mathbf{x}_n, y_n) = -y_n\cdot\log{\hat{y}_n} - (1-y_n)\cdot\log(1-\hat{y}_n) J n ( x n , y n ) = − y n ⋅ log y ^ n − ( 1 − y n ) ⋅ log ( 1 − y ^ n ) Therefore
∂ J n ∂ y ^ = − y n y ^ n + 1 − y n 1 − y ^ n = y ^ n − y n y ^ ⋅ ( 1 − y ^ n ) \frac{\partial J_n}{\partial \hat{y}} = -\frac{y_n}{\hat{y}_n} + \frac{1-y_n}{1 - \hat{y}_n} = \frac{\hat{y}_n - y_n}{\hat{y}\cdot(1-\hat{y}_n)} ∂ y ^ ∂ J n = − y ^ n y n + 1 − y ^ n 1 − y n = y ^ ⋅ ( 1 − y ^ n ) y ^ n − y n We also know that h ( 2 ) = σ h^{(2)} = \sigma h ( 2 ) = σ σ ′ ( a ( 2 ) ) = σ ( a ( 2 ) ) ⋅ [ 1 − σ ( a ( 2 ) ) ] \sigma'\left(a^{(2)} \right) =
\sigma\left(a^{(2)} \right) \cdot \left[ 1 - \sigma\left(a^{(2)} \right) \right] σ ′ ( a ( 2 ) ) = σ ( a ( 2 ) ) ⋅ [ 1 − σ ( a ( 2 ) ) ]
∂ J n ∂ W 1 i ( 2 ) = ∂ J n ∂ y ^ ⋅ σ ′ ( a ( 2 ) ) ⋅ z i = y ^ n − y n y ^ n ⋅ ( 1 − y ^ n ) ⋅ σ ( a ( 2 ) ) ⋅ [ 1 − σ ( a ( 2 ) ) ] ⋅ z i \begin{aligned}
\frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(2)}_{1i}} &= \frac{\partial J_n}{\partial \hat{y}} \cdot \sigma'\left(a^{(2)} \right) \cdot z_i\\
&= \frac{\hat{y}_n - y_n}{\hat{y}_n\cdot(1-\hat{y}_n)} \cdot \sigma\left(a^{(2)} \right) \cdot \left[ 1 - \sigma\left(a^{(2)} \right) \right] \cdot z_i
\end{aligned} ∂ W 1 i ( 2 ) ∂ J n = ∂ y ^ ∂ J n ⋅ σ ′ ( a ( 2 ) ) ⋅ z i = y ^ n ⋅ ( 1 − y ^ n ) y ^ n − y n ⋅ σ ( a ( 2 ) ) ⋅ [ 1 − σ ( a ( 2 ) ) ] ⋅ z i Using the fact that y ^ n = σ ( a ( 2 ) ) \hat{y}_n = \sigma\left(a^{(2)} \right) y ^ n = σ ( a ( 2 ) )
= ( y ^ n − y n ) ⋅ z i = (\hat{y}_n - y_n) \cdot z_i = ( y ^ n − y n ) ⋅ z i As a consequence, the partial derivatives w.r.t.
W ( 1 ) \boldsymbol{W}^{(1)} W ( 1 )
This example is an extension of Example 2. Instead of a binary
classification task, we consider a k k k
J n = − ∑ k = 1 K y k log ( y ^ k ) y ^ j = h ( 2 ) ( a j ( 2 ) ) = S ( a j ( 2 ) ) = exp ( a j ( 2 ) ) ∑ k = 1 K exp ( a k ( 2 ) ) \begin{aligned}
\mathrm{J}_n &= -\sum_{k=1}^K y_k \log (\hat{y}_k)\\
\mathbf{\hat{y}}_j &= h^{(2)}\left(\mathbf{a}^{(2)}_j \right) = \mathcal{S}\left(\mathbf{a}^{(2)}_j \right) = \frac{\exp\left(\mathbf{a}^{(2)}_j\right)}{\sum_{k=1}^{K} \exp \left(\mathbf{a}^{(2)}_k\right) }
\end{aligned} J n y ^ j = − k = 1 ∑ K y k log ( y ^ k ) = h ( 2 ) ( a j ( 2 ) ) = S ( a j ( 2 ) ) = ∑ k = 1 K exp ( a k ( 2 ) ) exp ( a j ( 2 ) ) We calculate δ j ( 2 ) \delta^{(2)}_j δ j ( 2 ) y ^ j \mathbf{\hat{y}}_j y ^ j a k ( 2 ) \mathbf{a}^{(2)}_k a k ( 2 ) ∂ J n ∂ a j ( 2 ) = ∂ J n ∂ y ^ j ∂ y ^ j ∂ a j ( 2 ) \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_j} =\frac{\partial \mathrm{J}_n}{\partial \hat{y}_j}\frac{\partial \hat{y}_j}{\partial a^{(2)}_j} ∂ a j ( 2 ) ∂ J n = ∂ y ^ j ∂ J n ∂ a j ( 2 ) ∂ y ^ j
$$
\begin{aligned}
\delta^{(2)}_j &= \frac{\partial \mathrm{J}_n}{\partial a^{(2)}j}
= \sum {k=1}^{K}\frac{\partial \mathrm{J}_n}{\partial \hat{y}_k}\frac{\partial \hat{y}_k}{\partial a^{(2)}_j}
\end{aligned}
$$
Here we obtain:
∂ J n ∂ y ^ k = − y k y ^ k \begin{aligned}
\frac{\partial \mathrm{J}_n}{\partial \hat{y}_k} = -\frac{y_k}{\hat{y}_k}
\end{aligned} ∂ y ^ k ∂ J n = − y ^ k y k and
∂ y ^ k ∂ a j ( 2 ) = ∂ ∂ a j ( 2 ) ( S ( a k ( 2 ) ) ) = ∂ ∂ a j ( 2 ) ( exp ( a k ( 2 ) ) ∑ i = 1 K exp ( a i ( 2 ) ) ) = S ( a k ( 2 ) ) ( I [ k = j ] − S ( a j ( 2 ) ) ) = y ^ k ( I [ k = j ] − y ^ j ) \begin{aligned}
\frac{\partial \hat{y}_k}{\partial a^{(2)}_j} &= \frac{\partial }{\partial a^{(2)}_j} \left(\mathcal{S}\left(a^{(2)}_k \right)\right)
= \frac{\partial }{\partial a^{(2)}_j} \left( \frac{\exp\left(\mathbf{a}^{(2)}_k\right)}{\sum_{i=1}^{K} \exp \left(\mathbf{a}^{(2)}_i\right) } \right)\\
&= \mathcal{S}\left(a^{(2)}_k \right) \left(\mathbb{I}[k=j] - \mathcal{S}\left(a^{(2)}_j \right) \right)\\
&= \hat{y}_k (\mathbb{I}[k=j] - \hat{y}_j)
\end{aligned} ∂ a j ( 2 ) ∂ y ^ k = ∂ a j ( 2 ) ∂ ( S ( a k ( 2 ) ) ) = ∂ a j ( 2 ) ∂ ⎝ ⎛ ∑ i = 1 K exp ( a i ( 2 ) ) exp ( a k ( 2 ) ) ⎠ ⎞ = S ( a k ( 2 ) ) ( I [ k = j ] − S ( a j ( 2 ) ) ) = y ^ k ( I [ k = j ] − y ^ j ) Therefore
δ j ( 2 ) = ∂ J n ∂ a j ( 2 ) = ∑ k = 1 K ∂ J n ∂ y ^ k ∂ y ^ k ∂ a j ( 2 ) = − ∑ k = 1 K y k y ^ k ⋅ y ^ k ( I [ k = j ] − y ^ j ) = − ∑ k = 1 K y k ⋅ ( I [ k = j ] − y ^ j ) = ( ∑ k = 1 K − y k ⋅ I [ k = j ] ) + ∑ k = 1 K y k ⋅ y ^ j = − y j + y ^ j ⋅ ∑ k = 1 K y k = y ^ j − y j \begin{aligned}
\delta^{(2)}_j &= \frac{\partial \mathrm{J}_n}{\partial a^{(2)}_j} = \sum_{k=1}^{K}\frac{\partial \mathrm{J}_n}{\partial \hat{y}_k}\frac{\partial \hat{y}_k}{\partial a^{(2)}_j}\\
&= -\sum_{k=1}^{K} \frac{y_k}{\hat{y}_k} \cdot \hat{y}_k (\mathbb{I}[k=j] - \hat{y}_j) \\
&= -\sum_{k=1}^{K} y_k \cdot (\mathbb{I}[k=j] - \hat{y}_j)\\
&= \left(\sum_{k=1}^{K} -y_k \cdot \mathbb{I}[k=j]\right) +\sum_{k=1}^K y_k \cdot \hat{y}_j \\
&= -y_j + \hat{y}_j \cdot \sum_{k=1}^K y_k \\
&= \hat{y}_j - y_j
\end{aligned} δ j ( 2 ) = ∂ a j ( 2 ) ∂ J n = k = 1 ∑ K ∂ y ^ k ∂ J n ∂ a j ( 2 ) ∂ y ^ k = − k = 1 ∑ K y ^ k y k ⋅ y ^ k ( I [ k = j ] − y ^ j ) = − k = 1 ∑ K y k ⋅ ( I [ k = j ] − y ^ j ) = ( k = 1 ∑ K − y k ⋅ I [ k = j ] ) + k = 1 ∑ K y k ⋅ y ^ j = − y j + y ^ j ⋅ k = 1 ∑ K y k = y ^ j − y j Where we have use the fact that ∑ k = 1 K y k = 1 \sum_{k=1}^K y_k = 1 ∑ k = 1 K y k = 1
∂ J n ∂ W j i ( 2 ) = ( y ^ n j − y n j ) ⋅ z i \frac{\partial \mathrm{J}_n}{\partial \boldsymbol{W}^{(2)}_{ji}} = (\hat{y}_{nj} - y_{nj}) \cdot z_i ∂ W ji ( 2 ) ∂ J n = ( y ^ nj − y nj ) ⋅ z i Figure 1: Example feed-forward neural network with one hidden layer.
Bishop, C. M. (2006). Pattern Recognition and Machine Learning . Springer-Verlag New York. https://link.springer.com/book/9780387310732